Our own AI film studio. The GPU bill is $0.
Watch the 49-second story
Video couldn't load. Open the film directly.
Read the film transcript
These puppets have a $0 GPU bill. Startup credits cover it right now. Good acting is another problem. Three weeks ago, we asked Claude to direct one ad. Then came a fraudster series: 29,000 views across platforms.
But every discarded take cost more money. So we kept Claude directing and ran Cosmos on GPUs rented through Modal. One measured five-second take: about 57¢ at list rates, before credits. Loading costs extra. That makes another try affordable. Now the hard part: choosing.
Motion checks find jumps. Qwen looks for visible mistakes. Claude ranks the takes. But a clean take can still miss the scene. We review the actual cut. Our recipe and films are on the blog. Get Sweat AI.
We started by asking Claude to direct an ad. Now our fraud-film series has 29,000 views across platforms, and we run our own video models on rented GPUs. Startup credits currently cover the GPU bill. Here is how we made another take affordable, and learned to judge what came back.
One experiment became a film series.
Three weeks ago, we started exploring what Claude Opus 5.5 could do with motion graphics. The surprise was how useful it became at editing and directing, too: planning scenes, choosing shots and working through a cut. We kept pushing until we had our first claymation ad.
The following week, we asked whether this could become a regular source of films for our brand. We made stories about famous fraudsters and the people caught up in their schemes. Twelve films in five days became a series that has now collected 29,000 views across platforms.
We wanted to keep going. But every discarded take was another paid request. Could we keep Claude as director and run the video model ourselves?
Series view total as of 9 October 2026. Part 2 keeps its original five-day snapshot.
Make room for another take.
The previous production week cost $184 in hosted image and video requests, including rejected takes and experiments. That encouraged us to try open-weight models we could run ourselves.
We now run NVIDIA's Cosmos 3 on GPUs rented through Modal. We applied for startup programs and secured credits; Modal's credits cover our current GPU generation and screening charges. Voice, image services and Claude calls are separate.
Even without those credits, a retake is affordable: one measured B200 request produced about five seconds of native 720 × 1280 video for roughly 57¢. Model loading and idle time add to the bill.
- GPU bill today
- $0
Grants cover GPU generation and screening.
- One measured take
- ≈ 57¢
Five seconds at 720 × 1280, using fifty inference steps.
- 32 similar takes
- $18.29
Eight shots, four takes each. Generation only.
Batching spreads the overhead.
Example cost per take, before credits- 1 take
- $0.93 per take, including illustrative overhead
- 4 takes
- $0.66 per take, including illustrative overhead
- 8 takes
- $0.62 per take, including illustrative overhead
- 32 takes
- $0.58 per take, including illustrative overhead
Cost assumptions, credit programs and the earlier $184 week
Our CosmosFull test generated 121 frames at 720 × 1280 and 24 fps. The request took 275.76 seconds, including 275.47 seconds of inference, and used up to 139,714 MiB of GPU memory. Other shots may take longer or finish sooner.
Modal's 8 October list prices were $0.001736/s for a B200, $0.0000131/s per physical CPU core and $0.00000222/s per GiB of RAM. Our four-core, 128-GiB configuration totals $0.00207256/s; the cost estimates here use the approximate rate of $0.0020725/s. At that rate, generation is $0.5715126, loading is $0.168017575, and a full 90-second warm tail is $0.186525. The chart adds model loading and one full tail to the batch, then divides by its take count.
Modal bills for model loading and the time a worker waits idle before shutting down. We call that the warm tail. Keeping the weights on a persistent volume avoids downloading them each time; batching spreads startup costs across more takes. Stopping the worker sooner can reduce idle charges. The chart assumes one loaded worker making takes in sequence; parallel workers can each incur those costs.
The $0 figure covers GPU charges. Voice, image generation, music, Claude calls, storage, subscriptions, local compute, publishing and our time fall outside that figure. Future GPU usage may need fresh credits or cash. Modal's startup program lists the eligibility rules and how to apply. AWS, Google Cloud and Azure credits do not directly cover Modal usage.
The earlier $184 week was actual cash spent on hosted APIs, including rejected takes and experiments beyond those twelve films. Our newer ledger estimates grant-funded compute, including tests and repairs. The totals cover different work and measure different kinds of spending.
Claude still directs. The crew changed.
We kept the earlier approach: Claude develops the story, plans the shots and directs the edit. Before it writes, we now build a research brief.
Find a reason to tell it now.
One scout compares recent Wikipedia attention with the previous four weeks and checks news headlines. We separately search circulating videos, saving their dates, public counters and original sources. A new repost can carry an old story.
Output: a lead, its source and why it caught our eyeTake the storytelling apart.
Agents read transcripts alongside frame sheets: the first three seconds, the change in the problem, the reveal and the ending. We compare those observations with retention from our own films, separately for each platform.
Output: an opening and a reason to keep watchingCheck the claim. Stage the action.
We link claims to court records, official statements or original reporting. A recent payment-fraud story needed a crucial distinction: a missing required copay did not establish that no childcare happened. Supported claims become visible puppet actions.
Output: sourced narration and a shot planWhat we extract from a reference film
Our research tool makes a dense sheet of the first three seconds at four frames per second, a whole-film sheet at 1.5-second intervals, scene-cut notes and a local transcript. Agents read them together: what is promised at the opening, what makes the next beat necessary, and where the answer arrives.
Our own review separates the hook, the transition into the story, the body and the ending. It compares platform-specific results with earlier medians and marks posts under 24 hours old as early. Retention curves led us to inspect the seconds after the last spoken line and shorten the ending. That is an editing hypothesis, not proof that the change increased reach.
The brief links each claim to its source and states what that source can establish. A missing payment can become an empty tray beside a stamped form. Public counters are snapshots; these small observational studies have not given us a reliable forecast of a film's reach. The research tools are part of our private engine, separate from the public generation helper below.
Once the narrative is written, we make a keyframe for each shot and give Cosmos 3 one visible action to animate. Each shot keeps its cast references beside the motion prompt and intended action. We generate four takes with different seeds.
In our puppet trials, we still preferred Kling's acting. Cosmos made retries cheaper, but a hand could change shape or a prop could vanish. More footage meant more to inspect. We needed a critic.
From shot plan to finished film
- Story + keyframeStarting image · cast · intended action
- Four takesCosmosFull · B200
720 × 1280 · 24 fps - Inspect + chooseGPU critic · defect checks
Claude ranks takes separately - Cut + reviewChecked narration · phone-v2 captions
Review the finished file
Under the hood: models and generation settings
Each film.json project keeps the narration with its cast references. It saves the motion prompts and selected clip windows, plus captions and sound. Sources and posting details live there too. The Python engine can pick up from a saved stage. The GPU app we inspected loads weights from a persistent volume, starts vLLM-Omni in its container and calls 127.0.0.1/v1/videos/sync. It sends the finished video back to the local project. Mounting an output volume does not by itself prove that a video was saved there.
The latest integration defaults to modal-full. Earlier projects used different defaults and lower resolutions. We still need to check the running worker: its settings can differ from the source.
| Stage / model | Pinned revision | Container | Limits in source |
|---|---|---|---|
| Full generationnvidia/Cosmos3-Super-Image2Video | 580f3f28… | B200 4 CPU · 128 GiB RAM | 2 containers · idle 90 sStartup 40 min / call 30 min |
| Preview generationnvidia/Cosmos3-Super-Image2Video-4Step | 237df5c6… | B200 4 CPU · 128 GiB RAM | 1 container · idle 90 sStartup 40 min / call 20 min |
| Semantic criticQwen/Qwen3-VL-8B-Instruct | 0c351dd0… | L40S 4 CPU · 32 GiB RAM | Default 3 containers · idle 60 sStartup 15 min / call 10 min |
Each model class has its own container limit. The studio code we inspected has no shared limit across all GPU workers. The source notes below list the full model revisions and runtime image.
For the full model, we request 121 frames at 720 × 1280 and 24 fps: about 5.042 seconds. We set fifty inference steps, guidance 6 and flow shift 5. Flow shift is easy to miss: the runtime version we checked defaulted to 10. The full model uses our negative prompt. The distilled preview model has a fixed schedule and ignores that prompt, so the two models need different settings.
Full-model settings · example request
model:          Cosmos3-Super-Image2Video
steps:          50
guidance_scale: 6.0
flow_shift:     5.0
width:          720
height:         1280
num_frames:     121
fps:            24
seeds:          [7, 21, 42, 99]
local_workers:  2
We give each shot one visible action, a fixed number of characters and a stable camera. The final pose needs to last long enough to cut. We ask for handmade faces and restrained movement, then add the stop-motion cadence in the edit. Asking for "jittery stop-motion" can produce glitches that the critic rejects.
Even a descriptive noun can become a prop. In earlier tests, "gold" made a paper bill sprout gold blocks. Mentioning "figures" summoned mannequins into an empty champagne shot. Spins and open-mouth expressions also gave the model opportunities to redraw handmade faces. We learned to describe the visible materials, keep one noun phrase per character, and avoid asking a rigid puppet head to perform a full turn.
Cheap retries need a good critic.
We can afford more takes. Now we have to inspect them. One check follows the pixels; Qwen, a vision-language model, looks for visible mistakes. Here is what each contributed to one real rejection.
This shot was meant to have nobody in it.
Watch the figures arrive. Then follow the checks and the rule that rejected it.
Video couldn't load. Open the take directly.
A pretty shot can still be the wrong shot.
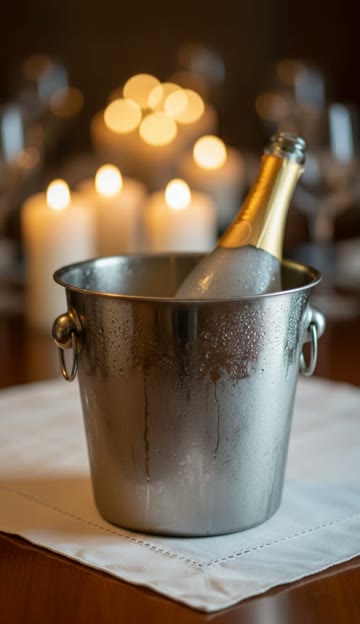
The opening has a bottle and an ice bucket. Wooden figures enter, then more shapes appear around the bottle. That breaks the brief.
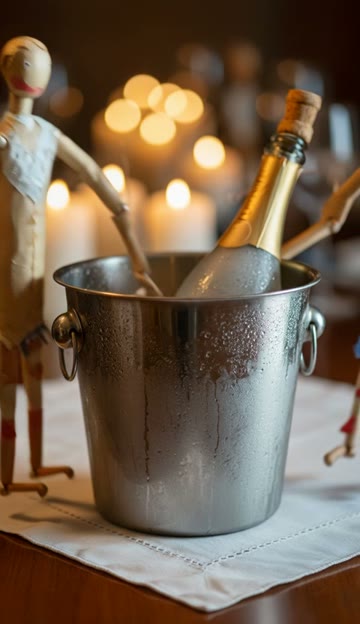
We want the studio to help us catch this before it reaches the edit.
Move through the take. See what changes.
Drag the timeline. Each pair is 1/24 second apart; the numbers measure what still differs after following the motion.
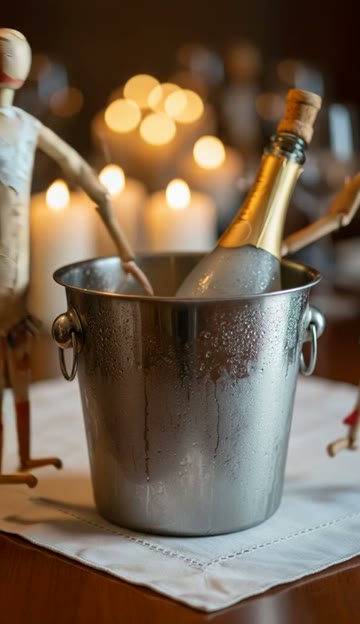
Arrow keys move one frame. Each stop updates the comparison and its measurements.
- Mismatch after alignment Warped LPIPS · unitless
- 0.0730At 0.40 or above, the hard-cut rule fires.
- Pixels without a reliable match Forward/backward motion check
- 5.50%At 90% or above, the other hard-cut rule fires.
This pair stays below both hard-cut lines. The take still failed the separate Qwen check.
No pair in this new scan crosses either hard-cut line. Yet the figures should never have entered. Qwen checks the different failure: figures in a scene meant to be empty.
How we measured this
- Follow the pixelsRAFT estimates motion in both directions.
- Line up the picturesUse the estimated motion to align the previous frame with the current one.
- Compare the aligned pictureLPIPS measures the remaining visual mismatch. A separate consistency check finds pixels without a reliable motion match.
Relative scan spike at this pair: 5.58. This compares the change with the clip's usual changes; it helps choose closer looks, rather than deciding rejection by itself.
121 decoded frames → 120 comparisons. Analysis normalizes the source to 720 × 1280, then scans at 360 × 640. The pictures above preserve the original aspect ratio.
We rescanned the archived source on 9 October 2026: 5.6 seconds of dense analysis on an L40S, with model loading separate. Qwen answers elsewhere are from the saved run. Download the measured series and method.
Now ask what went wrong.
Qwen sees selected pictures and answers ten Yes/No questions. The question picker shows its saved answers.
Normalized confidence in "Yes"; not a measured chance that Qwen is correct. This is a saved whole-clip answer. Scrubbing the video does not change it.
The saved run also took two closer looks, at the original frame rate. Jump to those recorded windows:
21 samples + 25 + 25 window frames = 71 appearances. Some pictures repeat across inputs.
This take failed screening.
The model's extra-figure answer alone crosses our fixed failure rule. Motion defects or a high-confidence answer in either short window can also reject a take.
A passing verdict and a quality score of at least 90 normally make a take eligible for Claude's separate comparison. That still does not prove the scene works.
Your turn: choose between two takes →Archived Tinder Swindler shot t06, preview seed 42. Download the saved record. No live model call is running here.
Inspect all ten stored answers and the input coverage
These are the whole-clip confidences from the archived run. The failure rule is ≥ 0.20. A high score means stronger confidence in a defect, not better video quality.
| Defect question | Confidence in Yes |
|---|---|
| Did an extra figure appear? | 0.9968 |
| Did a figure leave the frame? | 0.0759 |
| Did a face morph or flicker? | 0.0032 |
| Did an object appear or disappear? | 0.6225 |
| Did hands and props merge? | 0.3775 |
| Did an object duplicate? | 0.0953 |
| Did an object change shape? | 0.3208 |
| Did a body dissolve or wash out? | 0.0007 |
| Was there a hard cut or scene change? | 0.0012 |
| Did camera drift break the composition? | 0.0006 |
The two original-frame-rate windows cover frames 3–27 and 57–81, inclusive. Their highest defect confidences are 1.0 and 0.7773. The saved record reports 71 video frame appearances. The exact input receipt was not retained; the stored window bounds and answers are available in the record below. Three first-versus-later still comparisons were recorded separately, outside that counter. The archived quality score is 0.0, on a separate scale from these defect confidences.
Download the saved answers and thresholds. The source pictures and clip belong to this same archived preview; they are separate from our newer native-720p gallery.
The mannequin is an easy rejection. Choosing between two passing takes is harder.
Critic thresholds, sampling coverage and known blind spots
The archived preview has 121 decoded frames and 120 neighboring frame pairs. Qwen saw 71 frame appearances across its samples and windows. Some window frames also appear in the whole-clip samples, so a source frame can be shown more than once. Its highest window confidence at the original frame rate was 1.0.
The hard-cut rule fires at warped LPIPS ≥ 0.40 or occlusion share ≥ 0.90. A one-second freeze also fails. Qwen's Yes/No scores are not calibrated probabilities that its answer is correct. The ranker cannot explicitly reject every take; if it errors or times out, selection falls back to the highest quality score.
The critic runs motion checks and asks questions about the video. It decodes every frame at the original frame rate. RAFT optical flow estimates movement between frames; motion-warped LPIPS residuals measure what still differs after compensating for motion. Comparing forward and backward flow helps detect occlusion: pixels that no longer have a reliable match in the other frame. Simpler checks measure sharpness and exposure, and look for duplicate or black frames.
Qwen sees the whole clip at four frames per second, plus two short windows at the original frame rate around the largest changes in the motion scan. It answers ten defect questions; we turn its Yes/No next-token scores into normalized confidence values. It sees selected frames, even though the motion checks decode every frame.
- Default v1 gateFail at whole-clip defect confidence ≥ 0.20, window defect confidence ≥ 0.50, a dense hard cut or occlusion jump, or a one-second freeze. A failed take's quality score is capped at 49.
- Take eligibilityThe selector asks for both a passing verdict and a quality score of at least 90.
- Ranking viewFive frames at one fps, resized to 270 × 480, with candidate rows shuffled. Claude chooses a letter and explains why.
The two jobs are different. The critic checks for defects; the ranker chooses which take best serves the shot. A 99.6 quality score cannot tell us whether an embrace happened, whether a character stays recognizable across scenes, or whether the film holds our attention.
The default v1 critic also misses slowly changing faces, deformed hands, duplicated props and some objects passing through each other. In one older 25-clip test, it caught 89% of the labeled failures; in another 24-clip batch, it caught 33%. These small tests used limited labels, and we did not rerun them for this article. We need to test across model families before drawing broad conclusions.
An optional v2 review adds questions and checks that numerical answers are finite and within allowed ranges. It is not the current default. We also have a separate repair prototype that adds defect-specific instructions to the prompt and tries again. We have not verified a production run that connects it automatically to selection. Its estimated budget does not cap spending across the account.
A clean take can still miss the scene.
The scene calls for a nun to approach the man and embrace him. Both takes passed screening. The critic's quality score summarizes its defect checks on a 0–100 scale; higher is better. It does not tell us whether the embrace works. Watch both clips to the end. Which would you use?
Critic quality · out of 10099.6
Take A: later action
At 5.25–7.75 seconds, she leans toward him and holds his shoulder.
Critic quality · out of 10092.4
Take B: earlier embrace
Watch the white sleeve and hand around the embrace.
Different durations; each clip plays to its own end.
Which would you use for the embrace?
See Claude's choice and what it missed
Claude chose Take B, the 92.4 take, for its embrace and flagged the sleeve. But it compared seven early thumbnails, covering roughly the first five seconds. Its view omitted Take A's later leaning and shoulder holding. Its explanation was more certain than its view.
Today's ranker sees five thumbnails one second apart. That still leaves action unseen. These are older 480 × 832 clips, from the preview model (A, seed 7) and full model (B, seed 21). They illustrate an editing decision, not a controlled model benchmark.
Even a failed take can become the winner. In the current pipeline, when every take fails, the selector records an escalation but still ranks the rejected takes and copies a winner. Automatic prompt repair is a separate prototype. The warning does not stop selection.
The critic asks whether a take has defects. The ranker compares how the takes serve the scene. The edit decides which seconds the audience actually sees.
The edit is where the shot has to work.
The chapel edit used only 0.33–1.4 seconds of Take B, stretched into a 4.1-second shot. We need to review those seconds with the narration. An embrace elsewhere in the raw take cannot help the finished scene.
- Dimensions
- 720 × 1280
- Decoded video
- 121 frames · 24 fps
- File check
- SHA-256 recorded
Narration sets the cut. Word timestamps drive our phone-v2 captions: each spoken word gets a highlight. We hash the finished file so the review stays tied to what we publish.
Two fixes remain: stop selection when every take fails, and invalidate saved takes and scores when model versions or review rules change. Owning the workflow lets us make those changes ourselves.
Tracking files and stale results
Tracking a take and its final edit · pseudocode
intent = SHA256(image + prompt + negative_prompt + seed
                + model + app_class + width + height + frames + fps)

proof = {
  video_sha256: SHA256(returned_mp4),
  measured:     probe(returned_mp4),
  requested:    generation_contract
}

selected_sha256 == winner_sha256
reviewed_delivery_sha256 == uploaded_delivery_sha256
The hash we use to decide whether a take can be reused omits the weight revision and runtime image digest. Replacing the deployment under the same app/class name can therefore leave old takes reusable. The critic cache uses the filename, size, modification time in whole seconds, and intended action. It omits the complete video hash, critic weights and rubric version. Rewrite a file to the same size within a second, and its old score can survive.
We need to track the video alongside the model and rules that reviewed it. Changing the deployment or review rules should invalidate the relevant saved results.
Our newer test generates at 720 × 1280, then exports at 1080 × 1920 for Meta. That permitted 1.5× enlargement prepares the delivery file. It does not make older 480 × 832 footage meet the native-generation requirement, even if the export says 1080p.
Voice timing and final review
The earlier twelve-film workflow taught us to let narration set the timeline. Each beat is voiced separately through ElevenLabs and checked locally with Whisper against normalized words, requiring at least a 0.99 match unless an explicit mismatch is accepted. We preserve the voice's natural tempo. Shot boundaries are rounded from absolute times to frames, so rounding errors do not accumulate through the film.
Word timestamps drive the phone-v2 captions used in this companion film: short phrases in the Bricolage font, a yellow highlight on the spoken word and larger numbers. A caption_display mapping turns the spoken zero-dollar into $0 without changing its audio timing. Those choices live in the film project and caption profile, so rebuilding through the engine preserves the series' treatment.
FFmpeg cuts the selected clip windows, draws captions, mixes the music and effects, and exports the film. The current Meta recipe is H.264, constant 30 fps, BT.709, AAC stereo at 48 kHz and faststart. The source master uses 24 fps. We review the resulting file, including opening frames, eight frames across each final shot, and detail frames where needed.
Our review record includes hashes of the finished file, the assembly, its inputs and the review images. That keeps an approved frame sheet tied to the version it shows. An agent can fill in the record; it does not prove a human watched every second. We also ask: can we follow the action, do the characters remain recognizable, and does the film give us a reason to keep watching?
We can schedule an approved film for distribution. A separate worker claims due posts, retries recoverable failures and stops for inspection if it cannot tell whether a send succeeded. That helps avoid duplicate posts. We still choose the topic and judge the film.
Try it with one shot.
Start with one keyframe and one action. You can reproduce the generation request with the helper below, then follow the same screening and editing steps. Our full production engine and critic remain private.
Prepare your server and make four takes
- Prepare the model. Use the NVIDIA serving instructions with the full-model revision pinned below. On Modal, keep the weights on a persistent volume and load them once per worker. Our configuration is B200, four CPU cores and 128 GiB RAM.
- Generate four takes. Download the request helper and example prompt. Supply a 720 × 1280 PNG keyframe. The helper sends the 720 × 1280, 121-frame request with seeds 7, 21, 42 and 99, saving each MP4 with its timing and hash.
- Inspect, then edit. Review every take for changing faces, broken hands, missing props and the requested action. Our automated critic helps with the defect checks; Claude compares the survivors. Cut to the narration and review the finished file.
Against your running vLLM-Omni server
python3 generate_takes.py --keyframe keyframe.png \
  --prompt prompt.json --out takes-001
Setup and validation notes. The helper requests content guardrails; the server must support and enable them. We checked the helper offline without a new GPU run. The 57¢ measurement comes from our existing production request, not this helper.
Here is what came out of the studio.
Two recent films made with native 720p Cosmos footage, Claude's direction and the same caption treatment. Watch the acting, the props and how each cut lands with the narration.
Video couldn't load. Open the film directly.
The cow everyone blamed
Mrs. O'Leary, a fire and a story that outlived the evidence.
Download the filmVideo couldn't load. Open the film directly.
The one-copy album
Martin Shkreli and the one-copy Wu-Tang album.
Download the filmBoth films use Cosmos 3 full-model footage generated at 720 × 1280. These web copies keep the complete edits, burned-in captions and audio of the reviewed films. The older critic-comparison clips are separate examples.
We started by exploring what a new model could do. That became an ad, then a series, and now a studio we can keep using. Grants cover today's GPU bill; cheap underlying compute gives us room to keep trying. The last question is still the one our first ad taught us to ask: does the film say what we meant?
Sources and model versions
Technical snapshot: code and runtime inspected on 8 October 2026; story, research workflow, interactive critic and gallery updated on 9 October. Series views: 29,000 across platforms, updated 9 October. We used existing footage and file-bound records, and recomputed a dense motion scan for the interactive timeline. We did not rerun generation benchmarks or Qwen. Historical chapel clips, later native-720p footage and the new request helper have different scopes. The production engine, critic implementation and raw logs remain private.
- Full model
nvidia/Cosmos3-Super-Image2Video@580f3f28e33ba93c8d464768876da8c322619aad- Distilled preview
nvidia/Cosmos3-Super-Image2Video-4Step@237df5c63635ab171ad93fdde1d7f17fabae019a- Semantic critic
Qwen/Qwen3-VL-8B-Instruct@0c351dd01ed87e9c1b53cbc748cba10e6187ff3b- Generation runtime image
vllm/vllm-omni@sha256:970dee6658ea223f615b2438ce41e47f1d5322225482546e6e6bc5d8134f757c
Primary references
- Modal pricing supplies the published 8 October component rates; Modal for startups describes its credit program.
- The official vLLM-Omni repository and Modal's Volumes documentation explain model serving and persistent storage. The configuration notes above show the application settings we inspected.
- RAFT: Recurrent All-Pairs Field Transforms for Optical Flow and The Unreasonable Effectiveness of Deep Features as a Perceptual Metric describe the flow and perceptual-distance methods. Our decision thresholds are local engineering choices.
- The two preceding production accounts: Our first cut was adorable, but it said nothing and Twelve AI clay films in five days, for $184.
What you need to try this
You need authorized model access and a GPU deployment. Local media tools handle the edit. You also need Claude access and keyframes, with narration or reusable audio. A successful inference run does not settle model licensing or gated access. The audited Cosmos app disables its optional content guardrails because that stack's gated weights were not shipped; the visual-defect critic cannot substitute for content-safety review.
The downloadable helper reproduces the generation request against a server you prepare. It requests guardrails, unlike the audited production app described above. It does not install our studio, reproduce our private critic or guarantee the same output. Model revisions, container configuration and seeds are recorded so you can compare your run. Test one shot before a batch, keep the rejected takes, and review the exact cut you plan to publish.